


Knowing when to use noindex vs robots.txt is crucial for SEO. Noindex prevents pages from appearing in search results, while robots.txt controls crawler access. This guide explains their differences, best use cases, and practical tips.
Key Takeaways
Noindex prevents pages from appearing in search results while allowing search engines to crawl them, making it ideal for low-quality or duplicate content.
Robots.txt controls which pages search engines can access but doesn’t guarantee that disallowed pages won’t be indexed if linked from other sources.
Proper implementation of Noindex and robots.txt is crucial, and regular testing via tools like Google Search Console ensures effective SEO management.
What is Noindex?
Noindex is a directive. It is used to prevent a specific page from appearing in search results. It tells search engine crawlers that, while they can access the page, it should not be included in the search engine indexing and, therefore, will not appear in search results. This can be crucial for maintaining the quality of your search presence, especially when considering noindex vs other directives.
The noindex tag can be implemented via a meta tag or an HTTP response header. Adding the noindex instruction in the HTML head section or the X-Robots HTTP header is a common practice. This gives webmasters the flexibility to apply it directly in the source code or through server configurations. For instance, to ensure Google specifically handles the page as intended, the noindex meta tag can include the ‘googlebot’ directive.
Pages marked with noindex are still crawled by search engines, just not indexed. This means search engines see the content but do not show it in search results. This subtlety often makes noindex the preferred method for controlling visibility without blocking access entirely.
What is Robots.txt?
The robots.txt file is a powerful tool for managing how search engine crawlers interact with your website. Located at the root of a website, this txt file instructs search engines on which pages they can or cannot access. The primary goal of robots.txt is to manage the volume of crawler traffic to a site, which can prevent server overload.
Robots.txt files use Allow and Disallow directives to manage web crawlers access for users. The disallow directive stops crawlers from accessing specific URLs or patterns. This is particularly useful for blocking unimportant or sensitive parts of your site from being crawled, which can help optimize your site’s performance and ensure that only valuable content is indexed. Additionally, you can use txt disallow to further refine which areas of your site should not be indexed, including those requiring password protection. Furthermore, txt files can also be utilized to manage these directives effectively.
However, it’s crucial to understand that robots.txt does not prevent content from appearing in search results if it is linked from other pages. Therefore, while it can control crawling, it doesn’t guarantee that a disallowed page won’t be indexed. This distinction is vital for properly managing your site’s search engine visibility.
Key Differences Between Noindex and Robots.txt
Understanding the key differences between Noindex and Robots.txt is essential for effective SEO management. The noindex meta tag prevents content from appearing in search results, while the robots.txt file only directs search engines on what to crawl. This fundamental difference shapes how and when each tool should be used.
While blocking a page in robots.txt does not guarantee it won’t appear in search results, using the NOINDEX tag ensures that a page is excluded from search results. Search engines might still index a URL blocked by robots.txt if it is linked from other sites. This makes the NOINDEX tag more reliable for excluding pages from search results.
Placing the noindex tag in the HTML of a page prevents it from being indexed by search engines, whereas robots.txt is primarily used to manage crawling behavior for different purposes. For example, to stop a directory from being crawled, use the Disallow directive in robots.txt, while NOINDEX is used for preventing indexing of specific pages. These distinctions highlight the complementary but distinct roles of each tool.
When to Use Noindex
Knowing when to use Noindex can significantly enhance your site’s SEO strategy. Noindex is ideal for thin content pages, like those with minimal original text, as it helps maintain overall site quality by excluding low-value pages from search results.
Duplicate content can harm search engine rankings, and using Noindex on lower-quality versions of similar pages can prevent this issue. Noindex is also beneficial for thank-you pages, which usually have little unique content and can clutter search results.
Internal search results pages can create duplicate indexing issues, making them prime candidates for the Noindex tag. Additionally, during the development of a website, applying Noindex can prevent unfinished or low-quality pages from being indexed by search engines.
These scenarios illustrate the strategic use of Noindex to improve site description quality and search performance.
When to Use Robots.txt
Robots.txt is a powerful tool for managing crawler access to your website. It helps direct search engines on what to crawl or not, giving webmasters control over content accessibility. The disallow directive in a robots.txt file can prevent specified robots from accessing designated pages or directories, which is useful for managing crawler traffic effectively. Additionally, using default robots can further refine access control.
Blocking the crawling of unimportant or duplicate pages with robots.txt can enhance your site’s efficiency and improve overall performance. Additionally, robots.txt can be used to prevent specific files, like images or videos, from appearing in search results, thereby improving relevancy. This strategic control of site visibility is crucial for maintaining an optimized web presence.
Common Mistakes to Avoid
Despite the power of Noindex and Robots.txt, they can be misused if not handled correctly. A common mistake is combining both to block a page from indexing and crawling, which can lead to conflicting instructions. It’s generally advised not to combine noindex tags and robots.txt directives to avoid such conflicts.
If a webpage is still visible in search results after applying Noindex, it may be due to the page not being crawled since the tag was added. Additionally, if a page is blocked by robots.txt but has a noindex tag, the page might still get indexed. Ensuring that search engines can crawl a page to see the noindex tag is crucial.
Incorrect syntax in robots.txt rules can lead to misinterpretation by different crawlers, impacting your site’s search performance and connection to users. Using noindex, nofollow, and disallow commands incorrectly can significantly harm a website’s crawl budget and search visibility. Avoid these common pitfalls to ensure effective SEO management and adhere to txt rules.
Testing Your Noindex and Robots.txt Implementation
Testing your Noindex and Robots.txt implementation is crucial for ensuring that search engines handle your pages as intended. The Page Indexing report in Google Search Console helps track URLs that contain a Noindex directive. Using the URL Inspection tool allows you to see how Googlebot interprets your Noindex implementation.
You can test how robots.txt files affect indexing using Google Search Console. Regularly updating and testing your robots.txt file and Noindex tags ensures they align with your evolving SEO strategy and website content. Testing helps verify that your directives are effective in controlling crawling and indexing, including:
Ensuring alignment with your evolving SEO strategy
Matching your website content changes
Verifying the effectiveness of crawling and indexing directives
Best Practices for Using Noindex and Robots.txt
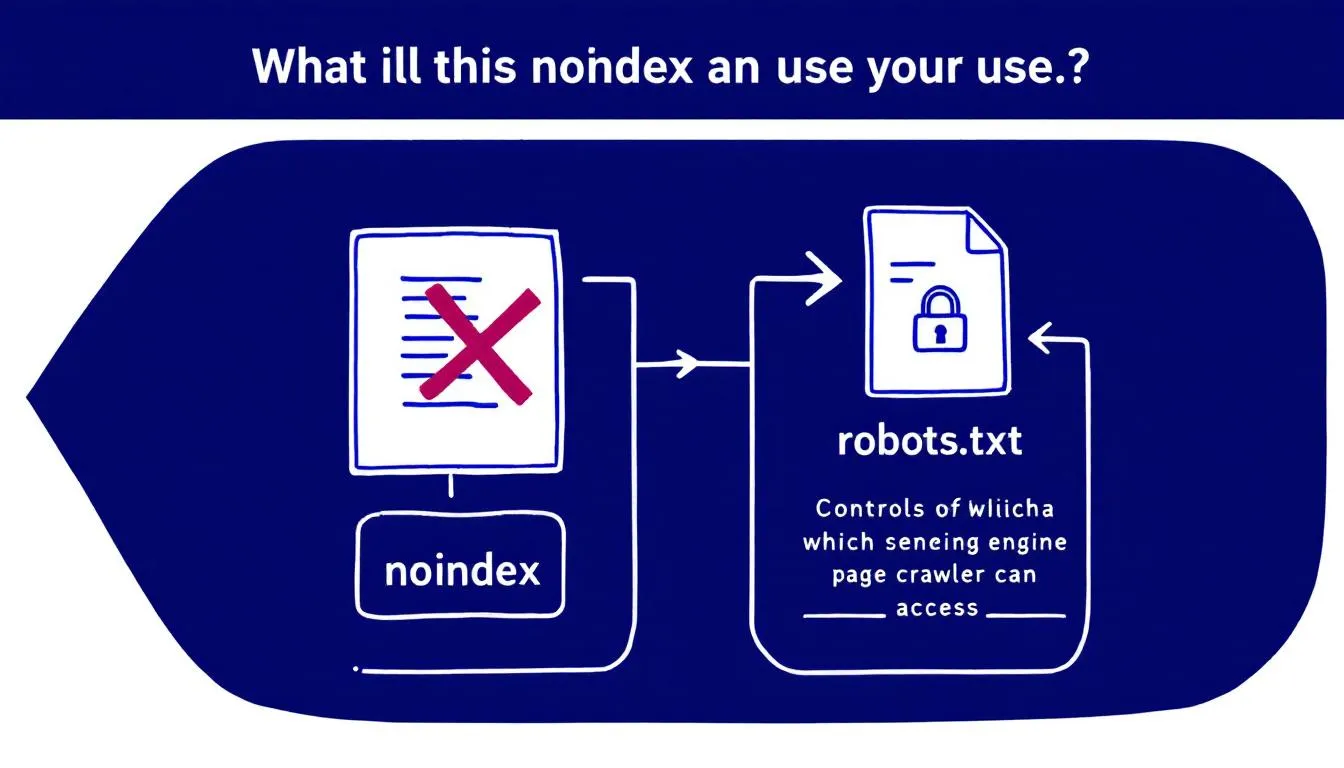
Following best practices for using Noindex and Robots.txt can significantly improve your site’s SEO. Google’s advice can help ensure your content appears in search results as intended. Keeping your directives updated and ensuring proper implementation is key to maintaining effective SEO.
To manage search engine access effectively:
Ensure that search engines can access the pages you want to Noindex.
Use robots.txt to manage crawler access strategically.
Regularly review and update your directives to instruct search engines and respond to how search engines interact with your website and SEO strategy.
Summary
Noindex and Robots.txt are essential tools for controlling search engine visibility and managing crawler access. Understanding their differences and knowing when to use each can significantly enhance your website’s performance and search engine rankings.
Proper implementation and regular testing are crucial. By following best practices and avoiding common mistakes, you can ensure that your site is optimized for search engines, delivering the best possible user experience and search visibility.
Frequently Asked Questions
What is the primary purpose of a Noindex tag?
The primary purpose of a Noindex tag is to prevent search engines from including a specific page in their search results, ensuring that it remains unindexed. This is valuable for managing which content is publicly accessible.
Can a page blocked in robots.txt still appear in search results?
Yes, a page blocked in robots.txt can still appear in search results if it is linked from other sites, as robots.txt controls crawling but not indexing.
How can I test if my Noindex tag is working correctly?
To ensure your Noindex tag is functioning correctly, utilize Google Search Console’s URL Inspection tool to verify how Googlebot interprets the directive. This method will confirm whether your page is excluded from indexing as intended.
What is a common mistake to avoid when using Noindex and Robots.txt?
Avoid combining Noindex tags with Robots.txt directives, as this can cause conflicting instructions and result in unintended indexing or crawling behaviors. Clear separation of these elements is key to maintaining proper site control.
Why should I regularly update my robots.txt file and Noindex tags?
Regularly updating your robots.txt file and Noindex tags is essential to align them with your changing SEO strategy and website content, ensuring effective control over which pages search engines crawl and index. This practice helps maintain optimal visibility and performance for your site.